---
### Author:  [@codinghorror](https://meta.discourse.org/u/codinghorror)
#### Post date: [2015年二月24日 16:59 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/2 "2015-02-24T16:59:31Z")
I believe @sam talked about adding some intermediate cache tables here. It is more difficult for us because we are doing random within a category, not random across all topics.
---
### Author:  [@riking](https://meta.discourse.org/u/riking)
#### Post date: [2015年二月24日 22:11 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/3 "2015-02-24T22:11:35Z")
The proposed solution is something like this:
- have a Redis key named after the category, for example `suggested:support/wordpress` (category.url)
- if we have N suggested topic slots to fill, try to RPOP n times
- if a RPOP returns nil (the list ran out), refill it:
- Query for a thousand topics
- LPUSH them all into the list 100 at a time (`LPUSH suggested:support/wordpress 123 54 87 35 78 15 64 79 ...`)
- Expire the key in 2 days or so
- Continue RPOPing until either we have N unique topic ids or it returns nil again.
- If RPOP returned nil again, and the category was specified, repeat the fill attempt, but use `suggested:@all` instead of a category-specific one
- Pass our topic ID list to Topic.find and then on to the serializer
This is also known as a “tetris random”.
---
### Author:  [@sam](https://meta.discourse.org/u/sam)
#### Post date: [2015年二月24日 22:13 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/4 "2015-02-24T22:13:25Z")
That is actually quite efficient and simple, I like it.
---
### Author:  [@sam](https://meta.discourse.org/u/sam)
#### Post date: [2015年二月25日 06:22 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/5 "2015-02-25T06:22:23Z")
This is now implemented per @riking’s suggestion
[https://github.com/discourse/discourse/commit/b760d22460ef5eef4c81b4ba4fbf1a8cdd384558](https://github.com/discourse/discourse/commit/b760d22460ef5eef4c81b4ba4fbf1a8cdd384558)
we backfill up to 3000 random items in the list and trigger a background refresh if the list is shorter than 500.
this technique works very efficiently for categories with a large number of topics, if categories are short then we round trip some extra data to redis, but its still more efficient cause we stabalize on issuing the backfill in the background.
---
### Author:  [@DeanMarkTaylor](https://meta.discourse.org/u/DeanMarkTaylor)
#### Post date: [2015年二月25日 14:24 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/6 "2015-02-25T14:24:18Z")
Thanks so much @sam - this update is a great improvement!
Here is a little more detail about what I get now.
###Initial Random Backfill
> **Executed in ~64.5ms (click to expand)**
>
> 
###Random Selection
> **Executed in ~6.2ms (click to expand)**
>
> 
###Total Topic Load Time
The total topic load time is now far lower at ~390ms to ~450ms


###In-category `ORDER BY topics.bumped_at`
This is now the slowest query in a topic load - loading somewhere between ~112ms and ~140ms.
> **Executed in ~112ms (click to expand)**
>
> 
###question
Is there any chance of the `topics.bumped_at` query being cached?
---
### Author:  [@codinghorror](https://meta.discourse.org/u/codinghorror)
#### Post date: [2015年二月26日 00:11 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/7 "2015-02-26T00:11:22Z")
Remind me again what the topic / post / user count is for your Discourse dataset? Visiting /about should be fine.
---
### Author:  [@DeanMarkTaylor](https://meta.discourse.org/u/DeanMarkTaylor)
#### Post date: [2015年二月26日 00:12 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/8 "2015-02-26T00:12:31Z")

---
### Author:  [@codinghorror](https://meta.discourse.org/u/codinghorror)
#### Post date: [2015年二月26日 00:17 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/9 "2015-02-26T00:17:25Z")
Hmm, surprising, does not seem that much higher than other sites we have, though all Discourse sites (that are not imports) cannot be too large as they have not had sufficient years to grow.
I know @sam was testing with a dataset that had 1 million topics (but not so many posts, proportionally) just to experience maximum pain. Surprised it is an issue with 40k..
---
### Author:  [@DeanMarkTaylor](https://meta.discourse.org/u/DeanMarkTaylor)
#### Post date: [2015年二月26日 00:19 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/10 "2015-02-26T00:19:24Z")
> [@codinghorror](#):
>
> Surprised it is an issue with 40k
Does the count on the about page include PM’s?
**There are also 101K of PM’s** - but that’s posts right?

---
### Author:  [@cpradio](https://meta.discourse.org/u/cpradio)
#### Post date: [2015年二月26日 00:19 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/11 "2015-02-26T00:19:59Z")
That’s a lot of PMs…
---
### Author:  [@codinghorror](https://meta.discourse.org/u/codinghorror)
#### Post date: [2015年二月26日 00:20 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/12 "2015-02-26T00:20:51Z")
Why are there 101,000 PMs? Yes that means your topic count is effectively 140k. Still nowhere near a million.
---
### Author:  [@DeanMarkTaylor](https://meta.discourse.org/u/DeanMarkTaylor)
#### Post date: [2015年二月26日 00:22 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/13 "2015-02-26T00:22:22Z")
> [@codinghorror](#):
>
> Why are there 101,000 PMs?
Users like their PM’s - over 11 years of users being active.
---
### Author:  [@sam](https://meta.discourse.org/u/sam)
#### Post date: [2015年二月26日 00:27 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/14 "2015-02-26T00:27:02Z")
stuff was way worse with a million, on my desktop it was 800ms for that query which is about 2 seconds on digital ocean
---
### Author:  [@DeanMarkTaylor](https://meta.discourse.org/u/DeanMarkTaylor)
#### Post date: [2015年二月28日 01:36 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/15 "2015-02-28T01:36:49Z")
> [@DeanMarkTaylor](#):
>
> Is there any chance of the topics.bumped\_at query being cached?
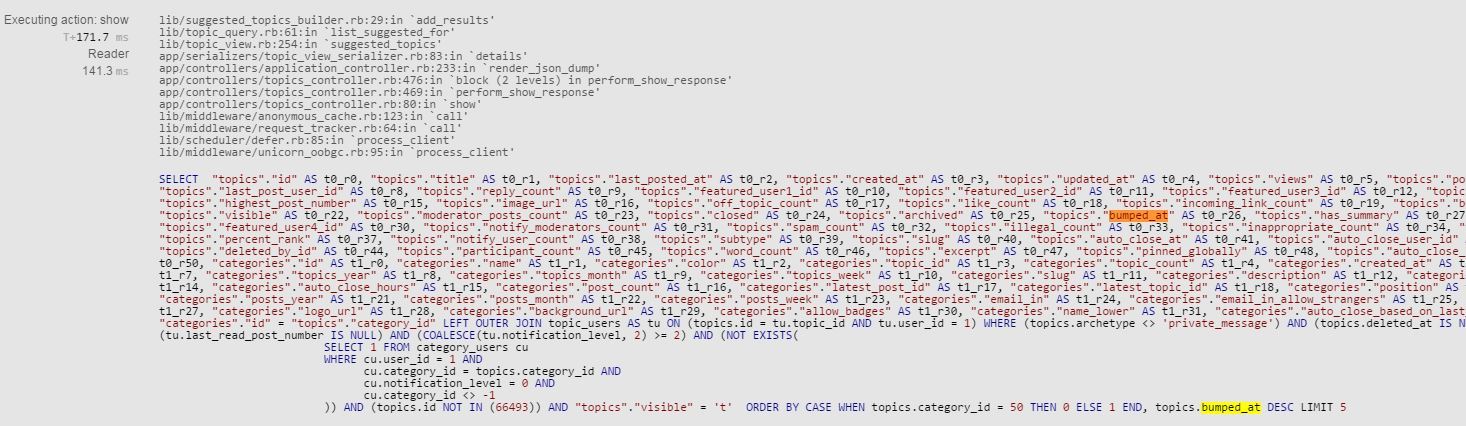
Out of interest in improving the `topics.bumped_at` `list_suggested_for` query I tested adding an index.
###Without Index
> **Executed in ~112ms (click to expand)**
>
> 
> **Executed in ~141.3ms (click to expand)**
>
> 
###With Index
> **Executed in ~13.2ms (click to expand)**
>
> 
> **Executed in ~18.7ms (click to expand)**
>
> 
###index tested
```SQL
CREATE INDEX idx_topic_load_suggested_for
ON topics
USING btree
(deleted_at, visible, archetype COLLATE pg_catalog."default", created_at);
```
###Tested table / index sizes
`topics` row count: 66,373
`topics` table size: 29MB
`idx_topic_load_suggested_for` index size: 3,488KB
###Thoughts and questions
To me it seems far better to scan only 3.5MB of data instead of 29MB per topic page load considering how frequently it occurs.
This was just a quick pass at what I thought was a matching index for the query - I’m sure someone with more knowledge of the details could do better.
**Is this an index the Discourse Team can get behind and perhaps include?**
Or is there a more cached solution that’s needed?
Perhaps just a good stop-gap?
---
### Author:  [@sam](https://meta.discourse.org/u/sam)
#### Post date: [2015年二月28日 01:54 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/16 "2015-02-28T01:54:35Z")
Totally open to improving indexing, but in this case I think a filtered index ׳where deleted at is null and visible׳ should work better
---
### Author:  [@DeanMarkTaylor](https://meta.discourse.org/u/DeanMarkTaylor)
#### Post date: [2015年二月28日 02:06 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/17 "2015-02-28T02:06:48Z")
I assume you mean this?
```SQL
CREATE INDEX idx_topic_load_not_deleted_and_visible
ON topics
USING btree
(deleted_at, visible)
WHERE (deleted_at IS NULL AND visible)
```
I tested this and the index doesn’t get used, it still does a Seq Scan of the table.
edit
I tried the original index with the addition of the `WHERE (deleted_at IS NULL AND visible)` constraint, it had no performance or index size impact as far as I could tell. But it did prevent the table scan.
---
### Author:  [@riking](https://meta.discourse.org/u/riking)
#### Post date: [2015年二月28日 02:48 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/18 "2015-02-28T02:48:38Z")
I think sam meant this:
```sql
CREATE INDEX idx_topic_load_suggested_for
ON topics
USING btree
(archetype COLLATE pg_catalog."default", created_at)
WHERE (deleted_at IS NULL AND visible);
```
---
### Author:  [@sam](https://meta.discourse.org/u/sam)
#### Post date: [2015年二月28日 03:01 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/19 "2015-02-28T03:01:55Z")
> [@DeanMarkTaylor](#):
>
> CREATE INDEX idx\_topic\_load\_suggested\_for
> ON topics
> USING btree
> (deleted\_at, visible, archetype COLLATE pg\_catalog.“default”, created\_at);
By default indexes in postgres are using btree so we don’t need that, also collation should be good so we don’t need that… What I want you to test is:
```plaintext
create index idx_topics_suggested_for
on topics (visible, created_at)
where archetype <> 'private_message' and deleted_at is null
```
This is a bit odd cause we are ordering on bumped\_at so I would assume
```plaintext
create index idx_topics_suggested_for
on topics (bumped_at)
where archetype <> 'private_message' and deleted_at is null and visible
```
Should work best, however admins see non-visible topics so perhaps adding it in makes sense.
What I am really struggling here with is why would you be adding deleted\_at to the actual index when the only valid value for it on selection is NULL. We are never ordering on deleted\_at
---
### Author:  [@DeanMarkTaylor](https://meta.discourse.org/u/DeanMarkTaylor)
#### Post date: [2015年二月28日 20:50 UTC](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619/20 "2015-02-28T20:50:54Z")
> [@sam](#):
>
> What I want you to test is:
###Best Results
Yes this gives the best results:
```SQL
create index idx_topics_suggested_for
on topics (visible, created_at)
where archetype <> 'private_message' and deleted_at is null
```
Index size: 1248KB
Method: Uses Index scan
Reduces the query time to: 6.7-5.8ms from 141.3-112ms
###Other Notes
####Note 1
In this query the index is not used because of the join reducing the result set before `bumped_at` is used / useful.
```SQL
create index idx_topics_suggested_for
on topics (bumped_at)
where archetype <> 'private_message' and deleted_at is null and visible
```
Index size: 896KB
####Note 2
The following index causes “recheck condition” on the `topics` table using bitmap heap scan after initially reducing the result set, causing slower total query time.
```SQL
create index idx_topics_suggested_for
on topics (created_at)
where archetype <> 'private_message' and deleted_at is null and visible
```
Index size: 896KB
####Note 3
> [@sam](#):
>
> What I am really struggling here with is why would you be adding deleted\_at to the actual index when the only valid value for it on selection is NULL. We are never ordering on deleted\_at
Yeah that would be because I’m used to not using INDEX’s that support WHERE conditions, you don’t need to be ordering on an item for it to help with index lookup performance in those cases.
[下一頁](https://meta.discourse.org/t/improve-performance-of-topic-load-order-by-random/25619.md?page=2)